AE 10: Iterating in R
Suggested answers
Packages
We will use the following packages in this application exercise.
- {tidyverse}: For data import, wrangling, and visualization.
- {rvest}: For scraping HTML files.
- {robotstxt}: For verifying if we can scrape a website.
Part 1: Iterating over columns
Your turn: Write a function that summarizes multiple specified columns of a data frame and calculates their arithmetic mean and standard deviation using across().
# A tibble: 3 × 5
species bill_len_mean bill_len_sd flipper_len_mean flipper_len_sd
<fct> <dbl> <dbl> <dbl> <dbl>
1 Adelie 38.8 2.66 190. 6.54
2 Chinstrap 48.8 3.34 196. 7.13
3 Gentoo 47.5 3.08 217. 6.48# include a default set of columns
my_summary <- function(df, cols = where(is.numeric)) {
df_summary <- df |>
summarize(
across(
.cols = {{ cols }},
.fns = list(
mean = \(x) mean(x, na.rm = TRUE),
sd = \(x) sd(x, na.rm = TRUE)
)
),
.groups = "drop"
)
return(df_summary)
}
penguins |>
select(-year) |>
my_summary() bill_len_mean bill_len_sd bill_dep_mean bill_dep_sd flipper_len_mean
1 43.92193 5.459584 17.15117 1.974793 200.9152
flipper_len_sd body_mass_mean body_mass_sd
1 14.06171 4201.754 801.9545Part 2: Data scraping
See the code below stored in iterate-cornell-review.R.
# load packages
library(tidyverse)
library(rvest)
library(robotstxt)
# check that we can scrape data from the cornell review
paths_allowed("https://www.thecornellreview.org/")
# read the first page
page <- read_html("https://www.thecornellreview.org/archive/")
# extract desired components
titles <- html_elements(x = page, css = ".entry-title a") |>
html_text2()
authors <- html_elements(x = page, css = ".n") |>
html_text2()
dates <- html_elements(x = page, css = ".published") |>
html_text2()
topics <- html_elements(x = page, css = ".entry-taxonomies") |>
html_text2()
post_urls <- html_elements(x = page, css = ".entry-title a") |>
html_attr(name = "href")
# create a tibble with this data
review <- tibble(
title = titles,
date = dates,
author = authors,
topic = topics,
url = post_urls
) |>
# format date variable
mutate(date = mdy(date))
# what we are iterating over
page_nums <- 1:10
cr_urls <- str_glue(
"https://www.thecornellreview.org/archive/page/{page_nums}/"
)
cr_urls
######## write a function to scrape a single page and use a map() function
######## to iterate over the first ten pages
# convert to a function
scrape_review <- function(url) {
# pause for a couple of seconds to prevent rapid HTTP requests
Sys.sleep(2)
# read the page
page <- read_html(url)
# extract desired components
titles <- html_elements(x = page, css = ".entry-title a") |>
html_text2()
authors <- html_elements(x = page, css = ".n") |>
html_text2()
dates <- html_elements(x = page, css = ".published") |>
html_text2()
topics <- html_elements(x = page, css = ".entry-taxonomies") |>
html_text2()
post_urls <- html_elements(x = page, css = ".entry-title a") |>
html_attr(name = "href")
# create a tibble with this data
review <- tibble(
title = titles,
date = dates,
author = authors,
topic = topics,
url = post_urls
) |>
# format date variable
mutate(date = mdy(date))
# export the resulting data frame
return(review)
}
# test function
## page 1
scrape_review(url = cr_urls[[1]])
## page 2
scrape_review(url = cr_urls[[2]])
# map function over URLs
cr_reviews <- map(.x = cr_urls, .f = scrape_review, .progress = TRUE) |>
list_rbind()
# write data
write_csv(x = cr_reviews, file = "data/cornell-review-all.csv")Part 3: Data analysis
Demo: Import the scraped data set.
cr_reviews <- read_csv(file = "data/cornell-review-all.csv")Rows: 80 Columns: 5
── Column specification ────────────────────────────────────────────────────────
Delimiter: ","
chr (4): title, author, topic, url
date (1): date
ℹ Use `spec()` to retrieve the full column specification for this data.
ℹ Specify the column types or set `show_col_types = FALSE` to quiet this message.cr_reviews# A tibble: 80 × 5
title date author topic url
<chr> <date> <chr> <chr> <chr>
1 CHEN | A Glimpse of Our Socialist Future: Hasa… 2026-10-05 Eric … Feat… http…
2 AOC Headlines Progressive “Students v. Billion… 2026-10-05 Isabe… Corn… http…
3 FAU Report – Public Engagement and Graduate Ed… 2026-10-05 Revie… Corn… http…
4 Provost Bala Releases “Future of the American … 2026-10-05 Revie… Corn… http…
5 The Black Pill: Political Kamikaze, Not Just S… 2026-09-30 Domin… Opin… http…
6 “Giving Hamas an Iron Dome:” Hasan Piker’s Tir… 2026-09-25 Eric … Camp… http…
7 Cornell Ranks 14th in U.S. News and Forbes 202… 2026-09-22 Revie… Beyo… http…
8 President Kotlikoff Wins Benson Award 2026-09-21 Revie… Beyo… http…
9 FIRE Grades Cornell with an “F” in the 2027 Fr… 2026-09-17 Revie… Corn… http…
10 Strict New Rules Imposed on Campus Organizatio… 2026-09-17 Revie… Camp… http…
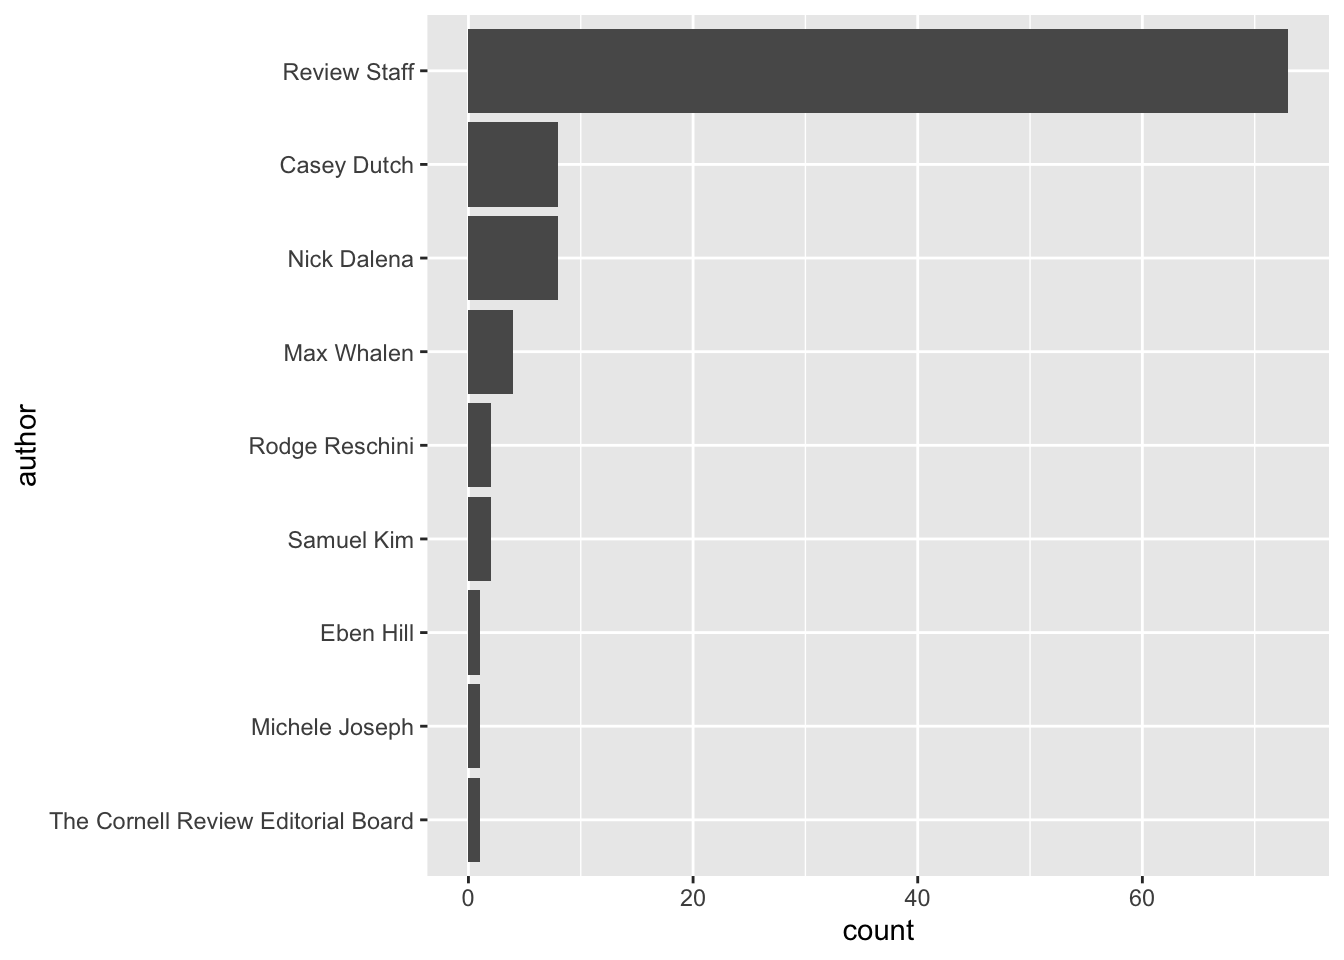
# ℹ 70 more rowsDemo: Who are the most prolific authors?
Demo: What topics does The Cornell Review write about?
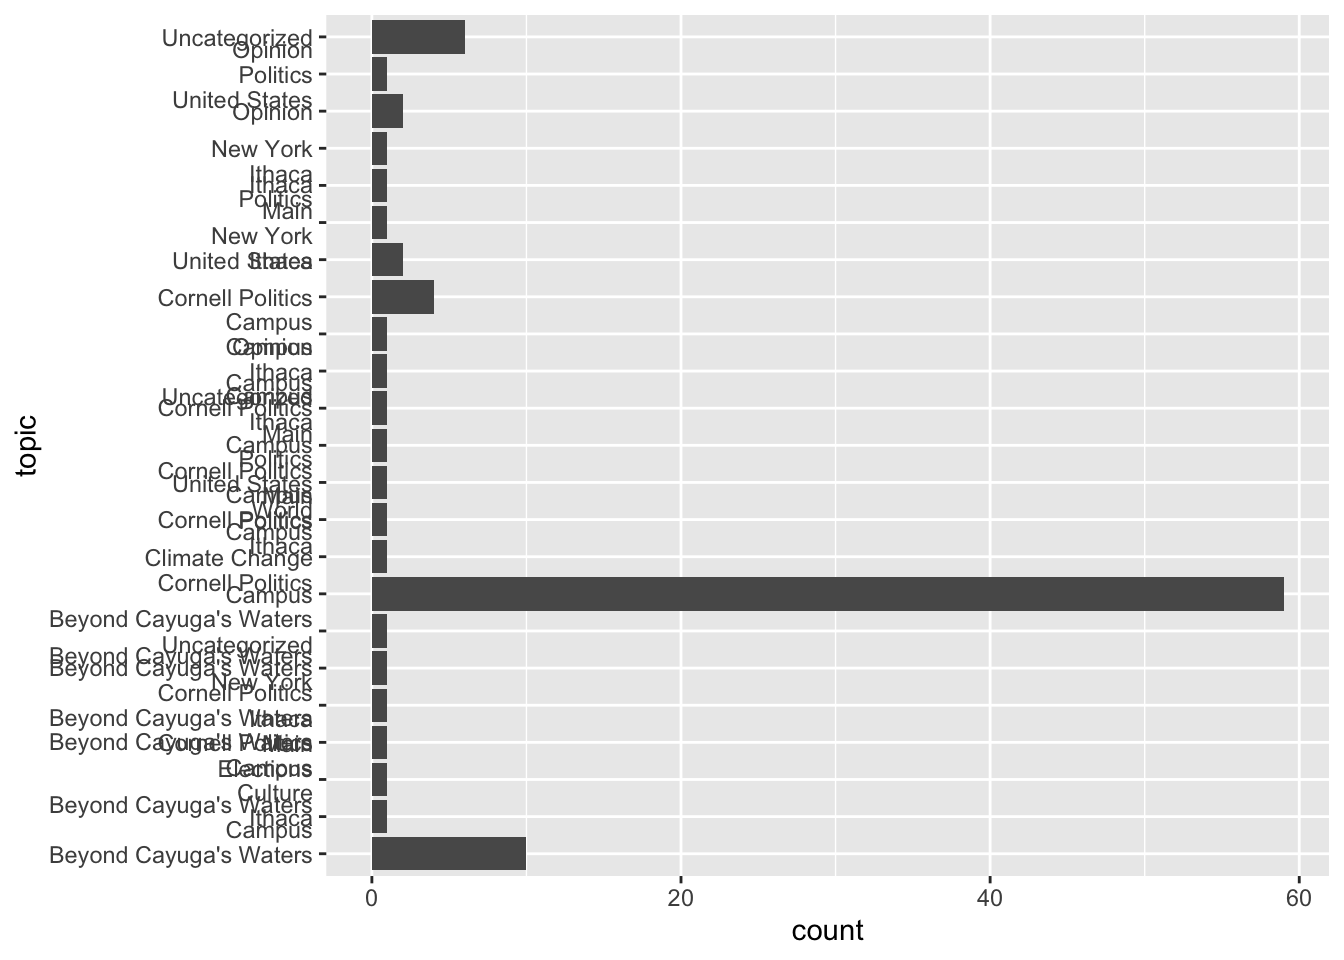
Not super helpful. Each article can have multiple topics. What is the syntax for this column?
cr_reviews |>
  select(topic)
# A tibble: 80 × 1
topic
<chr>
1 Featured | Opinion
2 Cornell Politics | Featured
3 Cornell Politics
4 Cornell Politics
5 Opinion
6 Campus | Featured
7 Beyond Cayuga's Waters
8 Beyond Cayuga's Waters
9 Cornell Politics
10 Campus | Featured
# ℹ 70 more rowsEach topic is separated by a "|". Since the number of topics varies for each article, we should separate_longer_delim() this column. Instead we can use a stringr function to split them into distinct character strings.
cr_reviews |>
  separate_longer_delim(
    cols = topic,
    delim = "|"
  ) |>
  mutate(topic = str_trim(string = topic))
# A tibble: 91 × 5
title date author topic url
<chr> <date> <chr> <chr> <chr>
1 CHEN | A Glimpse of Our Socialist Future: Hasa… 2026-10-05 Eric … Feat… http…
2 CHEN | A Glimpse of Our Socialist Future: Hasa… 2026-10-05 Eric … Opin… http…
3 AOC Headlines Progressive “Students v. Billion… 2026-10-05 Isabe… Corn… http…
4 AOC Headlines Progressive “Students v. Billion… 2026-10-05 Isabe… Feat… http…
5 FAU Report – Public Engagement and Graduate Ed… 2026-10-05 Revie… Corn… http…
6 Provost Bala Releases “Future of the American … 2026-10-05 Revie… Corn… http…
7 The Black Pill: Political Kamikaze, Not Just S… 2026-09-30 Domin… Opin… http…
8 “Giving Hamas an Iron Dome:” Hasan Piker’s Tir… 2026-09-25 Eric … Camp… http…
9 “Giving Hamas an Iron Dome:” Hasan Piker’s Tir… 2026-09-25 Eric … Feat… http…
10 Cornell Ranks 14th in U.S. News and Forbes 202… 2026-09-22 Revie… Beyo… http…
# ℹ 81 more rowsNotice the data frame now has additional rows. The unit of analysis is now an article-topic combination, rather than one-row-per-article. Not entirely a tidy structure, but necessary to construct a chart to visualize topic frequency.
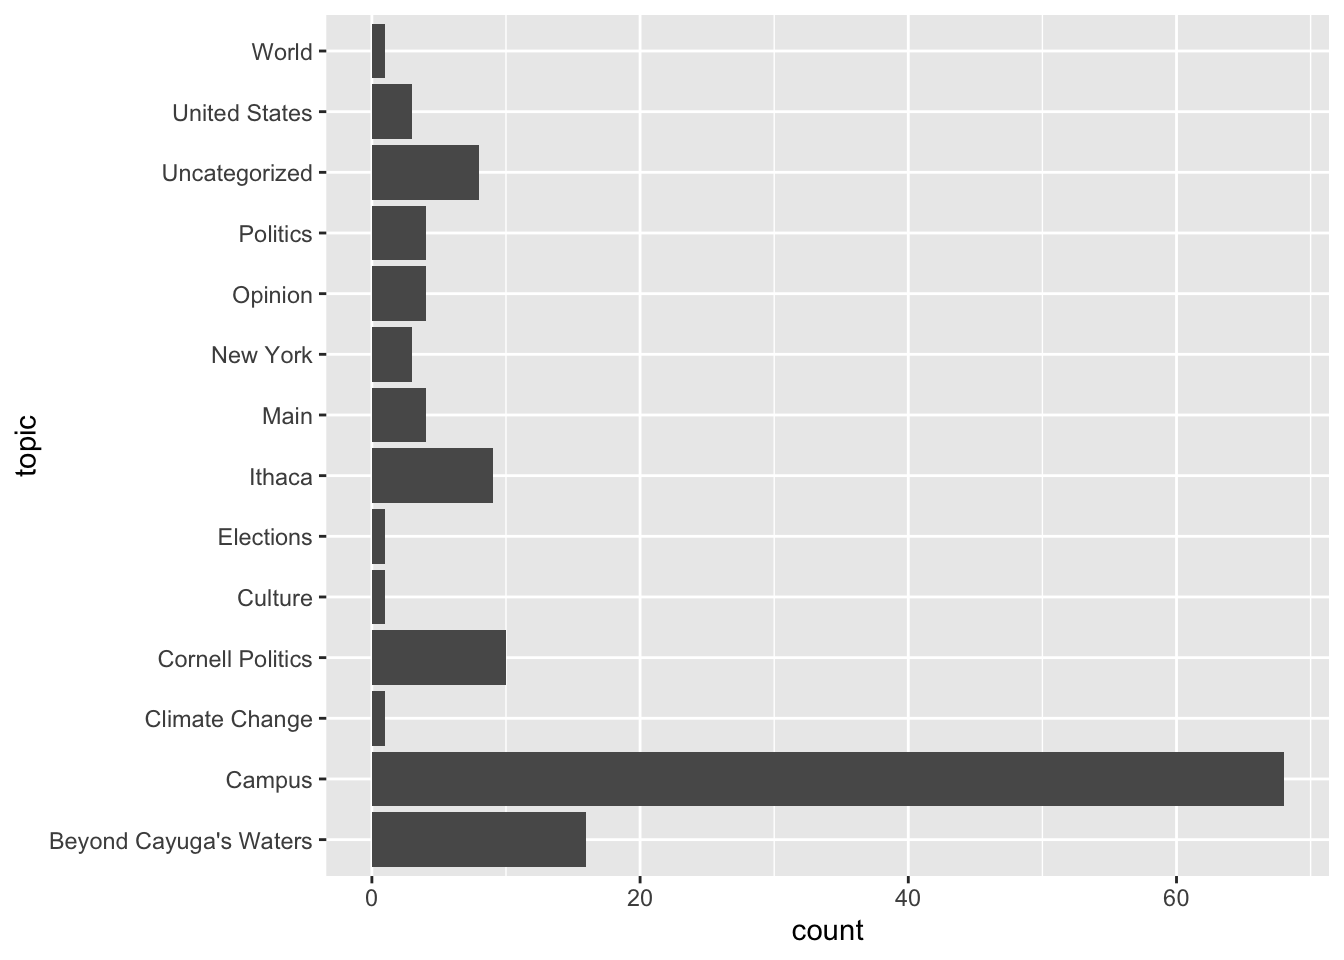
Let’s clean this up like the previous chart.
cr_reviews |>
  separate_longer_delim(
    cols = topic,
    delim = "|"
  ) |>
  mutate(
    topic = str_trim(string = topic),
    topic = fct_infreq(f = topic) |>
      fct_rev()
  ) |>
  ggplot(mapping = aes(y = topic)) +
  geom_bar()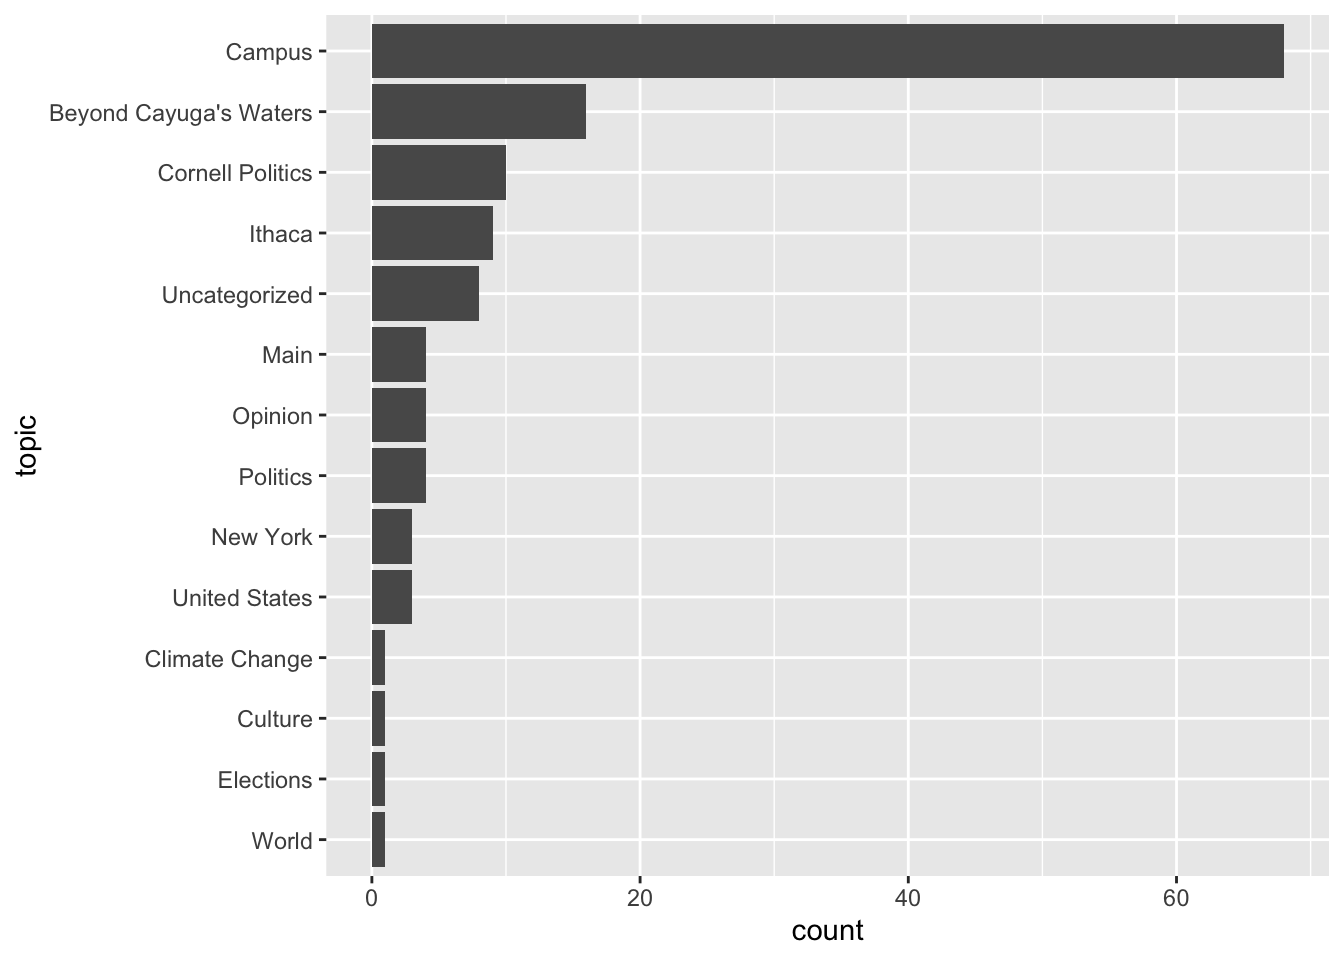
Acknowledgments
- Part 1 is derived from From R User to R Programmer and licensed under CC BY 4.0.
sessioninfo::session_info()─ Session info ───────────────────────────────────────────────────────────────
setting value
version R version 4.6.1 (2026-06-24)
os macOS Golden Gate 27.0.1
system aarch64, darwin23
ui X11
language (EN)
collate en_US.UTF-8
ctype en_US.UTF-8
tz America/New_York
date 2026-10-06
pandoc 3.10 @ /Applications/Positron.app/Contents/Resources/app/quarto/bin/tools/aarch64/ (via rmarkdown)
quarto 1.11.5 @ /Applications/quarto/bin/quarto
─ Packages ───────────────────────────────────────────────────────────────────
! package * version date (UTC) lib source
P bit 4.6.0 2025-03-06 [?] RSPM
P bit64 4.8.2 2026-05-19 [?] RSPM
P chromote 0.5.1 2025-04-24 [?] RSPM
P cli 3.6.6 2026-04-09 [?] RSPM
P crayon 1.5.3 2024-06-20 [?] RSPM
P digest 0.6.39 2025-11-19 [?] RSPM
P dplyr * 1.2.1 2026-04-03 [?] RSPM
P evaluate 1.0.5 2025-08-27 [?] RSPM
P farver 2.1.2 2024-05-13 [?] RSPM
P fastmap 1.2.0 2024-05-15 [?] RSPM
P forcats * 1.0.1 2025-09-25 [?] RSPM
P generics 0.1.4 2025-05-09 [?] RSPM
P ggplot2 * 4.0.3 2026-04-22 [?] RSPM
P glue 1.8.1 2026-04-17 [?] RSPM
P gtable 0.3.6 2024-10-25 [?] RSPM
P here 1.0.2 2025-09-15 [?] RSPM
P hms 1.1.4 2025-10-17 [?] RSPM
P htmltools 0.5.9 2025-12-04 [?] RSPM
P htmlwidgets 1.6.4 2023-12-06 [?] RSPM
P httr 1.4.8 2026-02-13 [?] RSPM
P jsonlite 2.0.0 2025-03-27 [?] RSPM
P knitr 1.51 2025-12-20 [?] RSPM
P labeling 0.4.3 2023-08-29 [?] RSPM
P later 1.4.8 2026-03-05 [?] RSPM
P lifecycle 1.0.5 2026-01-08 [?] RSPM
P lubridate * 1.9.5 2026-02-04 [?] RSPM
P magrittr 2.0.5 2026-04-04 [?] RSPM
P otel 0.2.0 2025-08-29 [?] RSPM
P pillar 1.11.1 2025-09-17 [?] RSPM
P pkgconfig 2.0.3 2019-09-22 [?] RSPM
P processx 3.9.0 2026-04-22 [?] RSPM
P promises 1.5.0 2025-11-01 [?] RSPM
P purrr * 1.2.2 2026-04-10 [?] RSPM
P R6 2.6.1 2025-02-15 [?] RSPM
P RColorBrewer 1.1-3 2022-04-03 [?] RSPM
P Rcpp 1.1.2 2026-07-05 [?] RSPM
P readr * 2.2.0 2026-02-19 [?] RSPM
renv 1.2.2 2026-04-16 [1] RSPM (R 4.6.1)
P rlang 1.3.0 2026-07-05 [?] RSPM
P rmarkdown 2.31 2026-03-26 [?] RSPM
P robotstxt * 0.7.15 2024-08-29 [?] RSPM
P rprojroot 2.1.1 2025-08-26 [?] RSPM
P rvest * 1.0.5 2025-08-29 [?] RSPM
P S7 0.2.2 2026-04-22 [?] RSPM
P scales 1.4.0 2025-04-24 [?] RSPM
P sessioninfo 1.2.4 2026-06-04 [?] RSPM
P stringi 1.8.9 2026-08-04 [?] RSPM
P stringr * 1.6.0 2025-11-04 [?] RSPM
P tibble * 3.3.1 2026-01-11 [?] RSPM
P tidyr * 1.3.2 2025-12-19 [?] RSPM
P tidyselect 1.2.1 2024-03-11 [?] RSPM
P tidyverse * 2.0.0 2023-02-22 [?] RSPM
P timechange 0.4.0 2026-01-29 [?] RSPM
P tzdb 0.5.0 2025-03-15 [?] RSPM
P utf8 1.2.6 2025-06-08 [?] RSPM
P vctrs 0.7.3 2026-04-11 [?] RSPM
P vroom 1.7.1 2026-03-31 [?] RSPM
P websocket 1.4.4 2025-04-10 [?] RSPM
P withr 3.0.3 2026-06-19 [?] RSPM
P xfun 0.60 2026-07-09 [?] RSPM
P xml2 1.6.0 2026-06-22 [?] RSPM
P yaml 2.3.12 2025-12-10 [?] RSPM
[1] /Users/bcs88/Projects/info-5001/course-site/renv/library/macos/R-4.6/aarch64-apple-darwin23
[2] /Users/bcs88/Library/Caches/org.R-project.R/R/renv/sandbox/macos/R-4.6/aarch64-apple-darwin23/46003b10
* ── Packages attached to the search path.
P ── Loaded and on-disk path mismatch.
──────────────────────────────────────────────────────────────────────────────